

Bring your own expert! Extending MoE models with new domain expertise
November 16th, 2026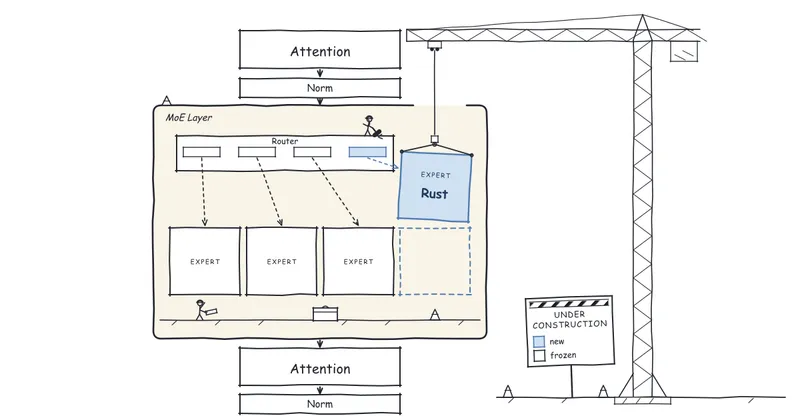
Many of today's state-of-the-art large language models use a Mixture-of-Experts (MoE) architecture: instead of one monolithic "brain", the model consists of many small subnetworks, or "experts", with only a fraction of them activating per token.
Our TNG AI research team keeps exploring how to efficiently adapt LLMs. So they asked: can we train our own experts and simply plug them into an existing model?
Find the answer in our newest article on Hugging Face.